
After listening to the lecture on understanding data and data analysis, I went straight into pandas practice.
Apparently the normal way to learn this is to download public data from the public data portal, read a CSV, and look at a DataFrame. Instead, we decided to first learn what a Series is and what a DataFrame is, then practice from there.
Table of contents
Open Table of contents
Project setup
I started with uv.
uv init --no-packageAdding --no-package initializes the project without the package configuration in pyproject.toml.
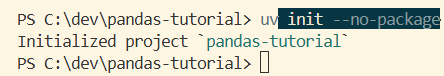
Then I added the libraries I needed.
uv add pandas numpy ipykernelRunning this creates a .venv folder, and the libraries get installed inside the Lib folder.
After that, I created install_check.ipynb and checked the install by confirming import worked.
import pandas as pd
import numpy as np
If Jupyter Notebook can’t find the virtual environment kernel — you can specify the Python interpreter path directly. I pointed it to
.venv/Scripts/python.exe.
What does pandas actually do
When structured data exists as a file, pandas is the library that converts it into a form Python can understand and lets you compute on it.
Structured data is usually in table form. A table is a 2D array, and pandas converts that table into a Python object. That object is the DataFrame.
A Series, meanwhile, is one component that makes up that table. When several Series come together, they form a table — a DataFrame.

So if you know how to handle a Series, you can extract column characteristics or pick out just the columns you need.
Series — a 1D array with an attached index
A Series is a 1D array with an index attached to it.
Comparing it with a Python list helped me understand it faster. Both are arrays, and both have indices. The difference is that a list’s index is already fixed, while a Series’ index can be set by us.
In spreadsheet terms, it corresponds to one column.
Here’s what creating one looks like.
pd.Series([72, 85, 90, 62])0 72
1 85
2 90
3 62
dtype: int64I wrote it horizontally, but it prints out vertically. The index gets attached automatically, and the data type is shown alongside it. This is the most basic form of a Series.
A Series isn’t a Python list, but there’s a lot you can do with it as if it were one.
| What you want to check | Method |
|---|---|
| Length | len() |
| Dimensions | ndim |
| Shape | shape |
| Index object | index (returns something like a RangeIndex) |
Since it’s an object, I expected I’d need to use a getter to pull values out, but surprisingly you can just do scores[0] like pulling from a list.
We decide the index
scores = pd.Series(
    [85, 90, 75],
    index=['student_a', 'student_b', 'student_c']
)
student_a 85
student_b 90
student_c 75
dtype: int64The index is an identifier, not a title
Here’s something that’s easy to get confused about. The index identifies a value — it’s not the title of the column. The name of the column is set separately with the name argument.
s = pd.Series(
    [3.2, 5.1, 10.0],
    index=['1월', '2월', '3월'],
    name='평균기온'
)
And indices can be duplicated.
sales = pd.Series(
    [100, 120, 150],
    index=['서울', '서울', '부산']
)sales.index.is_uniqueFalseis_unique checks whether there are duplicates in the index. In the example above, there are two 서울 entries, so it returns False.
Duplicates are allowed because, even with the same index, you can fetch by position, and you can also fetch everything that shares the same index at once.
sales['서울']서울 100
서울 120
dtype: int64It doesn’t return a single value — it returns a Series.
dtype — what happens when types mix
What happens when different data types get mixed inside a Series?
- Integer + float →
dtypebecomesfloat64 - Multiple types mixed together →
dtypebecomesobject
The problem with object is that arithmetic operations don’t work. Things like multiplying Series together get blocked.
If you want to fix a type, you can specify it with the dtype argument when creating the Series, or convert it afterward with astype().
Why bother converting to a Series at all
I was curious why you’d even bother converting an array into a Series, and the answer turned out to be it makes computation easier. That’s because internally it uses a numpy array.
If you just put in a comparison operator, it produces a bool, which you can then use for filtering and masking.
s[s > 15]Only the elements where s > 15 is True come out.
Adding by matching indices — the part that surprised me most today
When you add two Series together, pandas adds matching indices together. It’s index-based, not order-based.
a = pd.Series([1, 2, 3], index=['x', 'y', 'z'])
b = pd.Series([10, 20, 30], index=['z', 'y', 'x'])

a + b
x 31
y 22
z 13
dtype: int64Even though the order of b is reversed, x still becomes 1 + 30 = 31. It matched pairs by label, not by position.
So what happens to an index that only exists on one side?
c = pd.Series([1, 2], index=['x', 'y'])
d = pd.Series([10, 20], index=['y', 'z'])

c + d
x NaN
y 12.0
z NaN
dtype: float64At first I didn’t understand why NaN showed up. I expected 1 + 0, but that’s not what happened.
The side with no matching pair is treated as a missing value, not 0. It’s not interpreted as 1 + 0 but as 1 + NaN.
| Index | c | d | c + d |
|---|---|---|---|
| x | 1 | none | NaN |
| y | 2 | 10 | 12.0 |
| z | none | 20 | NaN |
Thinking about it, this makes sense. A missing value and a value of 0 are different things. It’s the same idea as what I learned in the lecture — that “0 is probably a measured value, so don’t convert it en masse”.
And since there’s at least one NaN in the result, even y, which added up normally, got converted from an integer to 12.0, a float.
Multiple ways to create a Series
Passing the second argument as the index — you don’t need the keyword, you can just pass it positionally.
values = [1200, 1500, 1700]
fruits = ['사과', '바나나', '딸기']

pd.Series(values, fruits)
values is treated as the values, and fruits is treated as the index.
You can also create one from a dictionary. This one surprised me a bit.
student = {
    "수학": 90,
    "과학": 90,
    "영어": 20
}

pd.Series(student)
Apparently you can also convert JSON into a dictionary this way, but you can’t drop it straight into a Series — you might need to flatten it first. (I haven’t tried this myself yet.)
Combining a dictionary with index lets you filter.
data = {
    '서울': 10,
    '부산': 20,
    '대전': 301,
    '천안': 235
}

labeled_data = pd.Series(data, index=['서울', '부산'])
Only Seoul and Busan, the ones specified in index, show up.
I double-checked one more thing here. If you include '대구' in index even though it’s not in data, it doesn’t throw an error. The Daegu row appears, but filled with NaN.
Same rule as the addition above. pandas aligns by index, and fills with NaN wherever there’s no match.
Things to study further
- The difference between tuples and arrays — a question that came up during practice. I want to lay out, all at once, how Python tuples, lists, numpy arrays, and pandas Series differ from each other.
[]vs..locvs..iloc— sincescores[0]just worked, I assumed it was fetching by position, but I need to check whether the same thing works on a Series with a manually assigned index. If looking up by label and looking up by position are different operations, I want to know when each one is used (pandas indexing docs).- Filling with 0 instead of
NaN— in this case, gettingNaNwas the correct behavior, but I want to know how to deliberately fill with 0 instead. I should check whetheradd()has something like afill_valueargument. - Why does the
objectdtype block operations — I learned that mixed types becomeobjectand block arithmetic operations, but I want to know what’s actually different under the hood. Worth connecting this to numpy array dtypes. - Why does an integer become a float when there’s a
NaNpresent — I suspect it’s becauseint64has no way to represent a missing value, but I need to confirm this. I’ve heard pandas has a separate nullable integer type,Int64(capitalized). - How duplicate indices are handled in practice — I understand duplicates are allowed, but I want to know whether people actually leave duplicate indices in place in real work, or whether they usually clean them up first.